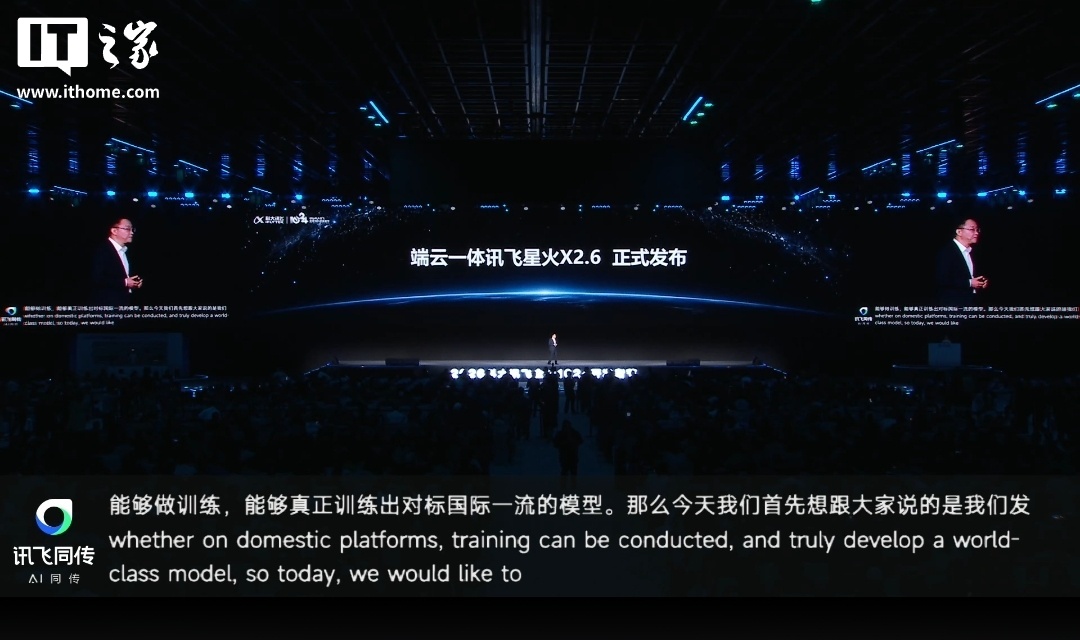
On October 22nd, at its annual iFlytek Global 1024 Developer Festival, Chinese AI firm iFlytek officially launched its latest large language model, iFlytek Spark X2.6. The company highlights the model’s end-to-end cloud integrated architecture and claims it represents a significant breakthrough in coding and agent capabilities, developed entirely using China’s own computing infrastructure.
Breakthrough on National Computing Power
Unlike many other large language models that rely on NVIDIA GPUs for training, iFlytek Spark X2.6 was developed and trained on Chinese computing platforms. iFlytek Chairman Liu Qingfeng emphasized that their model is unique in this regard, being the smallest in size among comparable models trained on such domestic infrastructure.
Furthermore, iFlytek Spark X2.6 has successfully overcome efficiency bottlenecks in training long-term tasks on national chips. The company has implemented a dynamic parallel training technology for extended tasks on domestic platforms, addressing the issue of low mixed-training efficiency caused by memory bandwidth limitations of national chips.
Innovations in Inference Performance
Regarding inference performance on national computing clusters for long-term tasks, iFlytek has introduced two key innovations:
- Distributed Inference Based on National Heterogeneous Computing Resources: This addresses the problem of slow training caused by memory bandwidth limitations of national chips.
- Development Based on National Hardware: This technology enables the reuse of existing inference results without the need for recalculations, significantly accelerating the process.
Opening Models to Developers
A notable release is the open-source model for edge devices, Spark X2.6-4B. This model demonstrates a significant leap in agent capabilities on edge devices, outperforming its predecessor, Spark X2.5-4B, across all metrics. Since its public release on September 1st, the Spark X2.5-4B model has already entered the top 4 most popular open-source models for edge devices globally in terms of download numbers.
Technical Specifications and Pricing
The iFlytek Spark X2.6 series models are now available for trial use on iFlytek’s official website. They feature a MoE architecture with 293 billion parameters (A30B) and an extended context length of up to 1 million tokens. The model’s capabilities in coding and agent interaction are said to have reached the industry’s highest level. Additionally, professional security protection is provided, with the ability to customize security policies for specific task scenarios.
Pricing for Spark X2.6 is structured as follows:
- Input: 0.9 Yuan per million tokens (limited offer).
- Input cache hit: 0.08 Yuan per million tokens (limited offer).
- Output: 3.6 Yuan per million tokens (limited offer).
The open-source model Spark X2.6-4B for edge devices has shown significant improvements in coding, agent capabilities, large text processing, and multilingualism. It offers three new inference modes, and its inference efficiency within iFlytek’s own system reportedly surpasses ollama. Pricing for Spark X2.6-4B is free for a limited time.
Overall, the launch of iFlytek Spark X2.6 marks a crucial advancement in the development of large language models, particularly in its use of national computing resources and its commitment to making advanced technology accessible to a broad range of developers.
Source: ithome.com