iFlytek has officially launched Spark-Audio-1.0-Preview, a groundbreaking voice foundation large model trained on entirely domestic computing power. This new model aims to revolutionize how machines understand and process audio, moving beyond traditional text-based approaches.
Overcoming Limitations of Traditional Audio Processing
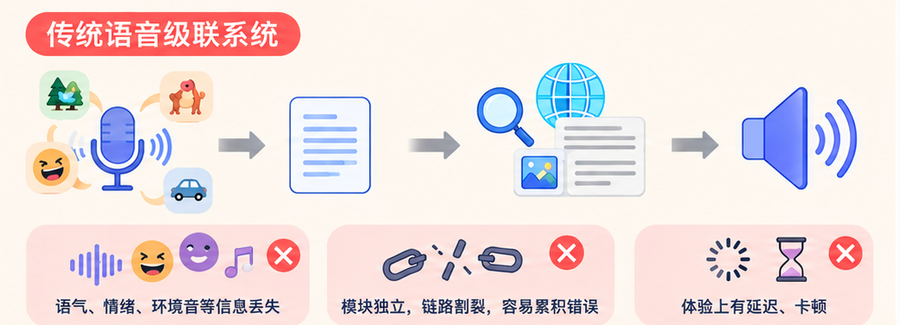
Historically, large models have processed audio through a cascaded approach: first converting speech to text, and then feeding that text to a language model for comprehension. However, this method suffers from two significant drawbacks:
- Information Loss: Text transcription captures only the spoken words, neglecting crucial nuances like tone of voice, emotional state, and background environmental sounds. This omission leads to incomplete scene understanding and compromises the final output quality.
- Fragmented Workflow: Capabilities such as speech-to-text, speaker recognition, and voice translation were handled as separate, sequential modules. This disjointed system not only made errors cumulative but also resulted in a subpar user experience with noticeable delays and stuttering.
Spark-Audio-1.0-Preview directly addresses these issues by understanding speech holistically. Instead of just transcribing, it directly interprets audio, comprehending human speech, environmental sounds, music, and more. Crucially, it can grasp the semantics, emotions, and context embedded within the sound, enabling machines to truly ‘listen and understand.’
Technical Specifications and Capabilities
The inaugural Spark-Audio-1.0-Preview features a 0.65B (Dense structure) audio encoder paired with a 30B-A3B (MoE structure) large language model. Trained on a massive dataset of 13 million hours of audio and extensive text data, all processed on a purely domestic computing cluster, this model represents a significant advancement in indigenous AI development. It supports multimodal input, accepting both text and voice simultaneously. Its capabilities span a wide range of tasks, including speech transcription, multilingual translation, multi-dialect recognition, environmental sound recognition, speaker identification, sentiment analysis, and complex audio question-answering. This allows machines to progress from merely ‘hearing clearly’ to ‘understanding deeply’.
iFlytek claims that Spark-Audio-1.0-Preview demonstrates competitive performance across various audio evaluation tasks, often exceeding expectations, particularly in challenging real-world scenarios like high-noise environments or low-volume speech. Its performance is remarkably close to larger, closed-source foundation models. Similar to the iFlytek Spark large model’s 1+N architecture, this voice foundation model can be fine-tuned to develop specialized models and systems for applications such as speech recognition, simultaneous interpretation, and voice interaction.
Performance Benchmarks and Comparative Analysis
Spark-Audio-1.0-Preview supports recognition for 99 languages and 202 dialects. In comparative tests, it has shown advantages in multilingual and multi-dialect speech recognition over models of similar size, such as Qwen3.5-omni-flash (35B-A3B). Its performance is also comparable to significantly larger models like Qwen3.5-omni-plus.
On benchmark datasets like Fleurs, Kespeech, and LibriSpeech for English, Chinese, multilingual, and multi-dialect speech recognition, Spark-Audio-1.0-Preview outperformed Gemini-3.1 Pro. Notably, it achieved State-of-the-Art (SOTA) results on the Fleurs-Chinese test set. In practical application scenarios, it exhibits a distinct edge in speech recognition tasks under complex conditions, including high noise and low volume.
While Spark-Audio-1.0-Preview maintains strong performance in general knowledge, math, and coding tasks without significant degradation, iFlytek acknowledges room for improvement in areas such as instruction following, dialogue, and audio comprehension. The company plans to further enhance its capabilities by addressing these areas while reinforcing its existing strengths.
Availability
Spark-Audio-1.0-Preview is now available for public testing. The corresponding API will be accessible through the iFlytek Open Platform in the near future.